We turn generative AI into reliable enterprise systems.
Stop deploying brittle chat demo toys. We engineer production-ready AI applications powered by private RAG pipelines, pgvector hybrid search, autonomous task agents, and strict deterministic validation guardrails that eliminate hallucinations.
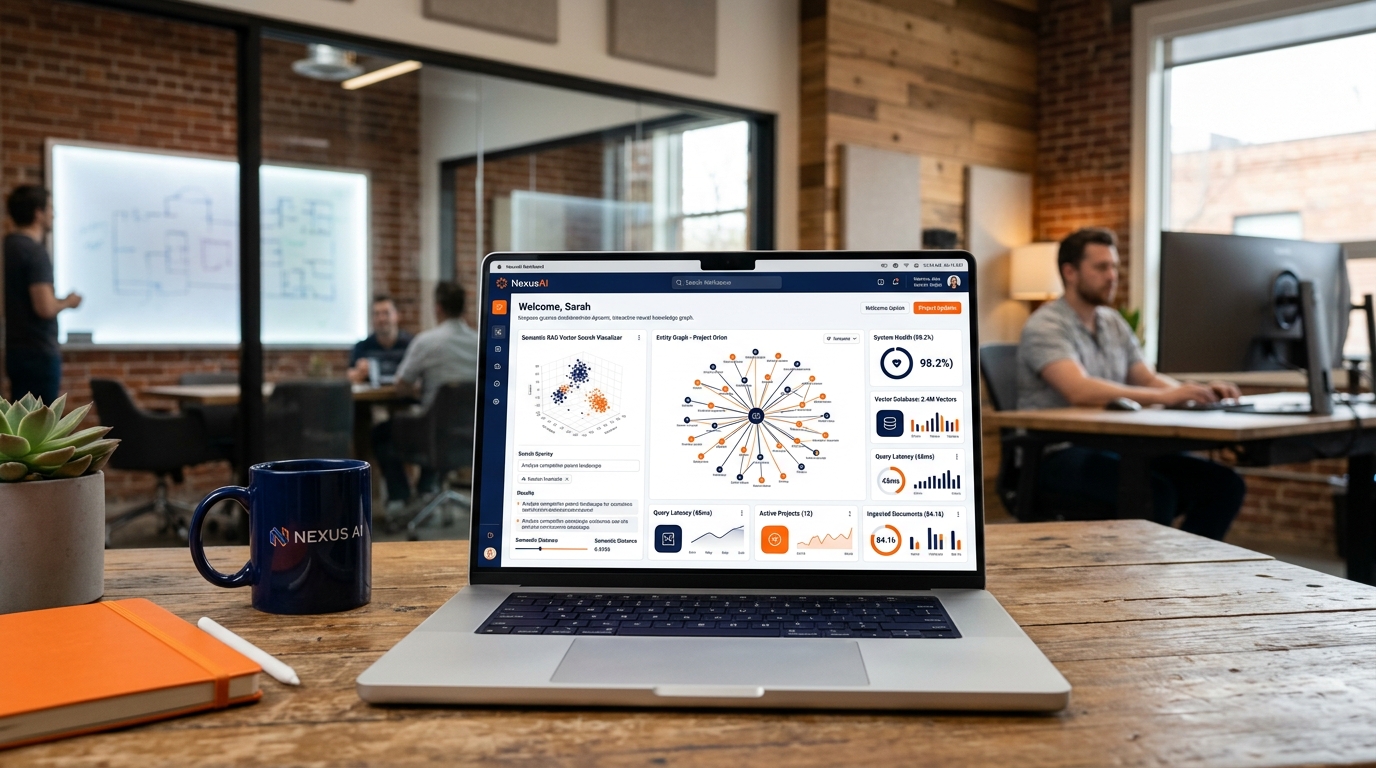
Engineered for accuracy, privacy, and speed.
We focus on pragmatic enterprise workflows that drive real efficiency gains without exposing proprietary company IP or introducing hallucinations into business operations.
Enterprise RAG & Semantic Search
High-precision Retrieval-Augmented Generation using PostgreSQL pgvector and Qdrant. Context-aware chunking, hybrid keyword/vector search, and metadata filtering over millions of documents.
Autonomous Task Agents
Multi-step autonomous agents built on LangGraph and CrewAI. Tool-calling agents that execute database lookups, trigger internal APIs, generate reports, and verify their own work before completion.
Private LLM VPC Deployment
Host open-weight foundation models (Llama 3.1, Mistral, Qwen) completely inside your own AWS / Google Cloud VPC via vLLM. Zero third-party data retention and guaranteed data sovereignty.
Intelligent Document Parsing
Automated extraction and classification of messy PDFs, purchase orders, medical records, and legal contracts into structured, validated JSON using vision models and layout parsers.
Deterministic Guardrails
Eliminate hallucinations and model drift with Pydantic / Zod strict schema enforcement, prompt injection firewalls, and programmatic fallback routes for mission-critical tasks.
Fine-Tuning & Domain Adaptation
Low-Rank Adaptation (LoRA / QLoRA) fine-tuning for domain-specific jargon, proprietary coding syntax, and specialized industry terminology to outperform generalist models at 10x lower cost.
How we deliver deterministic, production-ready AI systems.
We reject the "wrap an API and hope" methodology. Every AI system we ship is subjected to rigorous semantic evaluation, latency profiling, and edge-case boundary testing.
Data Auditing & Feasibility Scoping
We analyze your raw document formats, database structures, and workflow requirements to determine whether RAG, fine-tuning, or heuristic agent workflows are optimal.
- ✓ Data Cleanliness & Quality Audit
- ✓ Architecture Feasibility Report
- ✓ Accuracy Baseline & Success KPIs
Chunking & Vector Index Architecture
We engineer custom semantic chunking strategies tailored to your document structure, configure pgvector embeddings, and set up metadata indexing for sub-second retrieval.
- ✓ Semantic Token Chunking Strategy
- ✓ Vector Index & Distance Metric Tuning
- ✓ Hybrid Search & Reranking Pipeline
Semantic Evaluation & Benchmarking
Using the RAG Triad framework (Context Relevance, Groundedness, Answer Relevance), we run automated benchmarks against 200+ test queries to guarantee minimum 95%+ precision.
- ✓ RAG Triad Precision Benchmarks
- ✓ Negative Testing (Hallucination Traps)
- ✓ Latency & Cost Per Query Profile
Agent Orchestration & Guardrails
We wire the LangGraph state machine, integrate external tool APIs, configure Pydantic deterministic schema validation, and implement safety fallback heuristics.
- ✓ State Machine Agent Graph
- ✓ Tool Calling Execution Connectors
- ✓ Strict Output Validation Layer
UI/UX & Operator Copilot Interface
We build fast, responsive web or mobile interfaces featuring streaming tokens, source citation footnotes, interactive feedback buttons (thumbs up/down), and audit dashboards.
- ✓ Real-Time SSE Token Streaming UI
- ✓ Clickable Source Citation Badges
- ✓ Admin Telemetry & Flagging Console
Private VPC Deployment & Observability
Production deployment on your AWS / GCP infrastructure, automated vector reindexing schedules, LangSmith / OpenTelemetry monitoring, and 60 days of hyper-care support.
- ✓ 100% Private Cloud Infrastructure
- ✓ OpenTelemetry Query Tracing
- ✓ 60-Day Dedicated Hyper-Care SLA
The enterprise AI engineering toolchain.
Engineered with modern vector databases, high-throughput inference engines, and industrial-strength orchestration frameworks.
Vector DBs & Retrieval
Orchestration & Agents
Models & Inference
Evals & Observability
Skribe — Enterprise Audio Intelligence & Semantic Knowledge RAG
Engineered a multi-tenant enterprise voice and document intelligence platform that transcribes, diarizes, and indexes audio recordings into an encrypted pgvector semantic search engine. Enables instant retrieval across 10,000+ hours of team meetings with sub-second response times.
Common questions about enterprise AI product development.
Honest answers regarding data privacy, accuracy guarantees, and recurring inference costs.
Never. We use enterprise zero-data-retention agreements for proprietary foundation APIs (such as Azure OpenAI or AWS Bedrock), or deploy open-weight models (Llama 3.1 / Mistral) entirely within your private VPC with no outbound network access. Your confidential intellectual property remains 100% under your ownership and perimeter.
We implement a three-layer defense: (1) Strict Retrieval Grounding where models are instructed to answer only from verified chunk citations; (2) Pydantic/Zod structured schema output validation that rejects non-conforming responses; and (3) Automated RAG Triad evaluation pipelines that grade answers for groundedness before displaying them to end users.
By using efficient vector indexing in PostgreSQL (pgvector) and intelligent prompt compression with Cohere Rerank, most business applications process tens of thousands of queries for under $150 to $300 per month in LLM API tokens. For high-volume use cases, self-hosted open-weight models on reserved GPU instances reduce token costs by up to 80%.
A focused Enterprise RAG pipeline and copilot interface typically ships in 6 to 8 weeks. Autonomous multi-step agent workflows with custom tool integrations and private VPC fine-tuning launch in 10 to 12 weeks.
Yes. We provide clean REST, GraphQL, or Server-Sent Event (SSE) streaming endpoints with drop-in React/TypeScript UI components that embed seamlessly into your existing mobile apps, CRM, or customer portal.
Let's build an AI product that delivers verified business ROI.
Schedule a 30-minute technical evaluation directly with Nihar Ranjan Rout. We will discuss your data sources, retrieval architecture, privacy requirements, and a concrete prototype plan.
Location: Creuto HQ, Bhubaneswar, Odisha, India